
BotConnector Local
Run AI models on your own computer.
One command starts a private chat page on your machine. The model runs on your CPU or GPU, keeps working without internet, and can also answer chats you send from the BotConnector web app.
npx https://app.botconnector.id/device-cli-launcher-v1.0.2.tgz offline --allow-local-aiNeeds Node.js 22.12 or newer. Nothing else to install. Which models fit my computer?
Two ways to use the same model
The model always runs on your computer. Only the window you talk to it through changes.
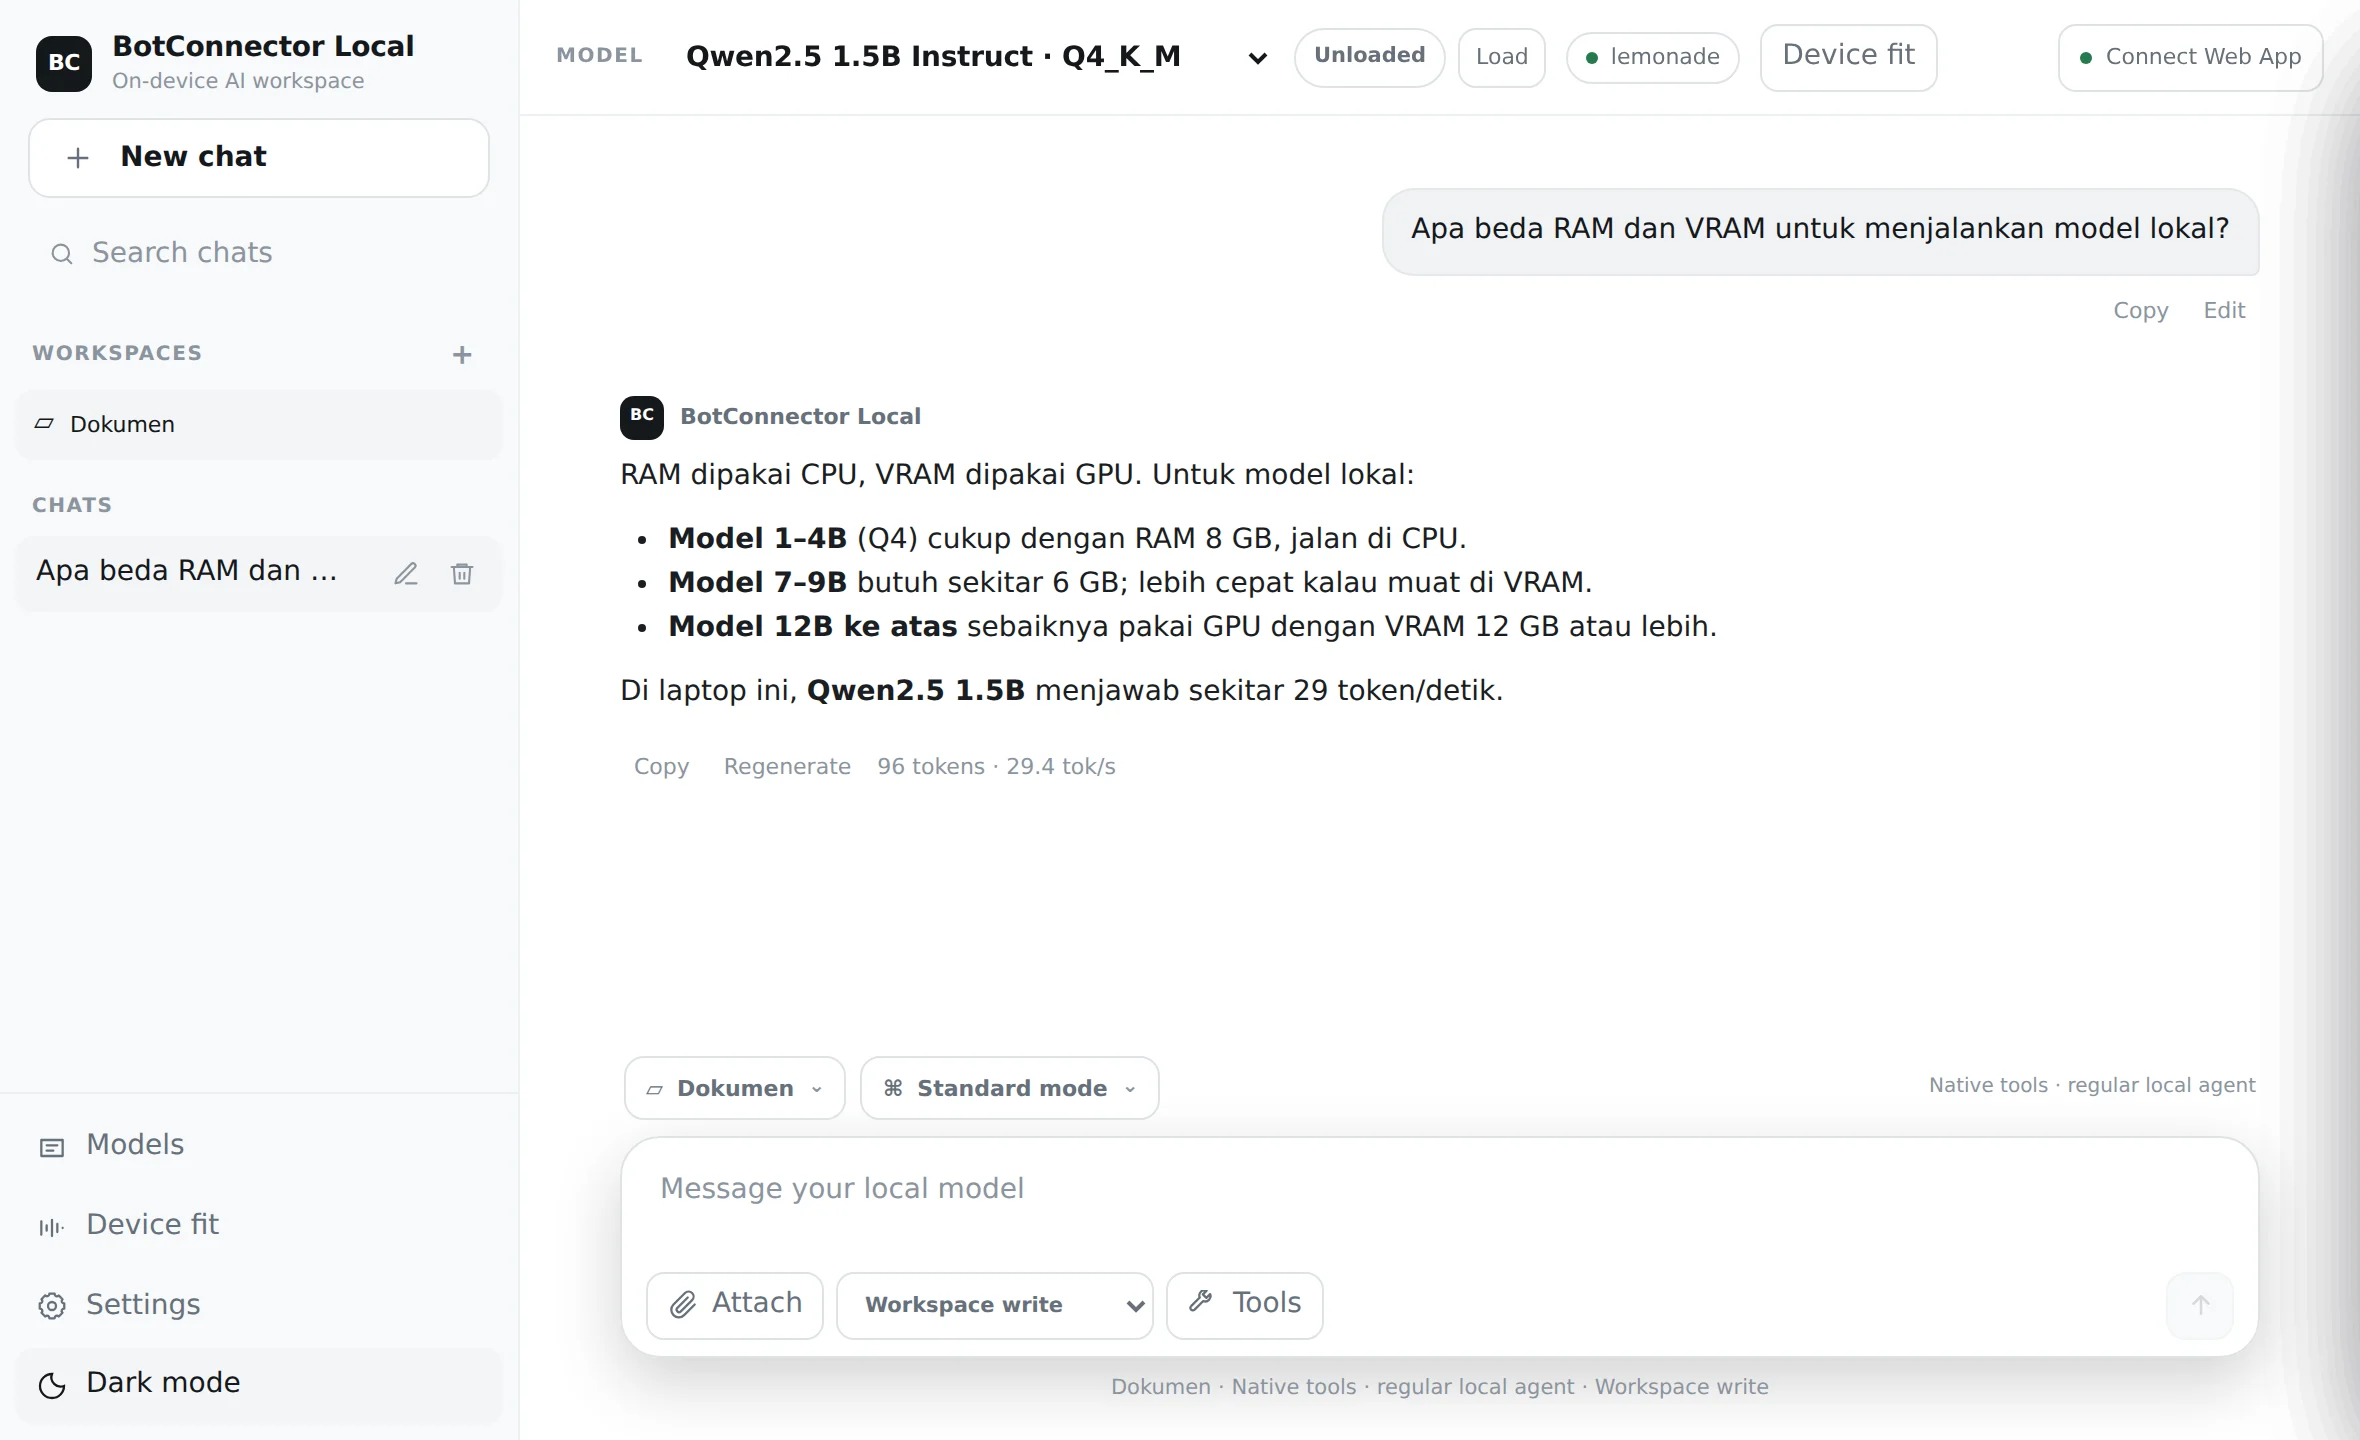
Offline, in your browser
A chat page at 127.0.0.1 with chat history, file attachments and model management. Works with the network cable pulled out.
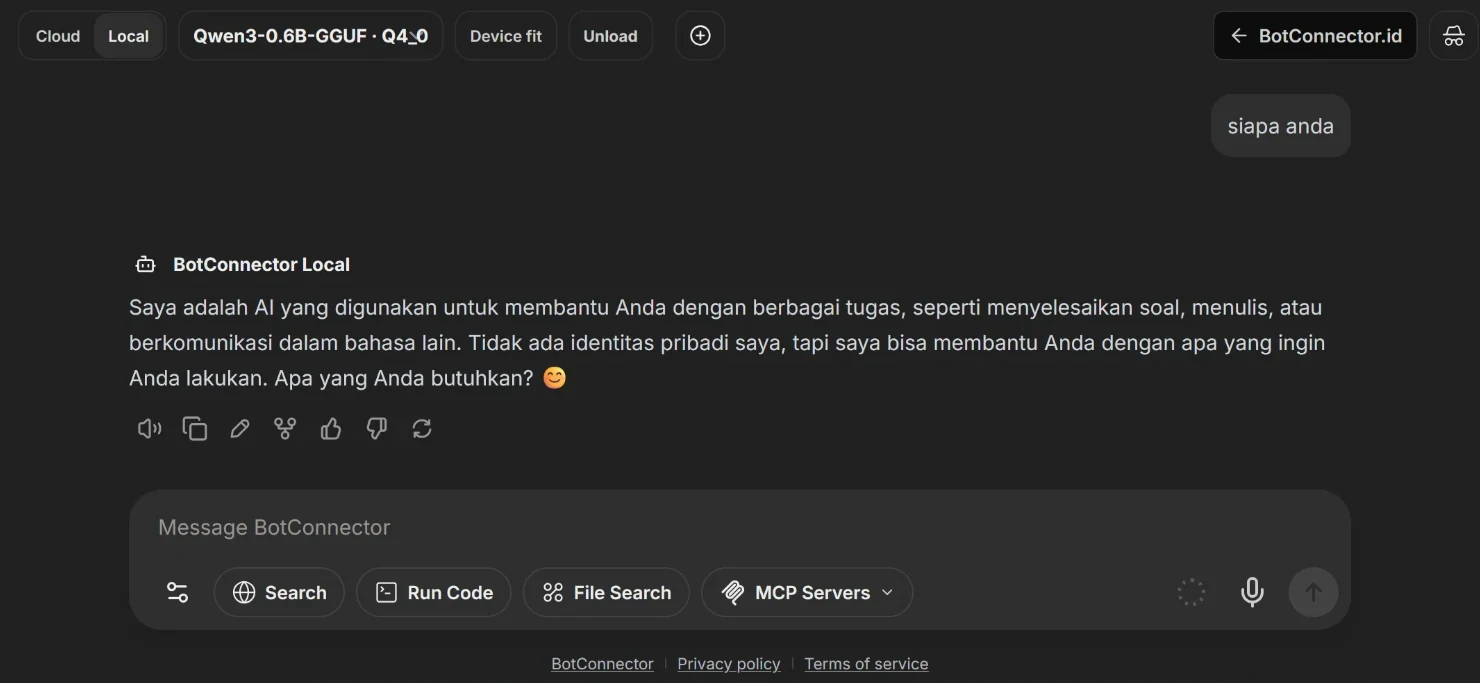
From the web app
Pair the device with a code from the web app and pick Local. Your messages go to your computer; the answer comes back to the web app.
Use Local AI with Switchboard, too
In addition to offline chat and the existing WebApp pairing above, models running through the original BotConnector Local Core can power Switchboard v0.4.2 agents on the same computer. This does not replace WebApp device pairing.
- Install or update Switchboard with
npm install -g @botconnector/switchboard@latest. - Open the bundled original model manager using
sbx local. Explicitly select and start a model; check status withsbx local status. - Run
sbx weband choose Settings → Models → Local AI to use a running model.
Switchboard uses your own local hardware, not the website server's GPU. GGUF model weights and runtimes are not downloaded automatically. If your local AI stops, Switchboard does not silently send your request to Cloud.
Explore Switchboard Local AI · v0.4.2 release / Windows portable
Getting started
- Open a terminal (PowerShell on Windows) and run the command above. A chat page opens in your browser.
- Open Models. BotConnector checks your RAM and GPU and marks each model great, ok or warn for this machine. Download one.
- Chat. To use the model from the web app, run the command with
connectinstead ofofflineand enter a pairing code from the web app. How to get the code.
Which engine runs the model
BotConnector uses what you already have:
- Lemonade or Ollama, if one is running.
- Otherwise it downloads the official llama.cpp build for Windows or Linux — the GPU build when it finds a GPU, the CPU build when it does not.
- On macOS, install Ollama first; BotConnector will use it.
Connect your computer to the web app
Pair once with a code. After that the device reconnects by itself every time BotConnector Local runs.
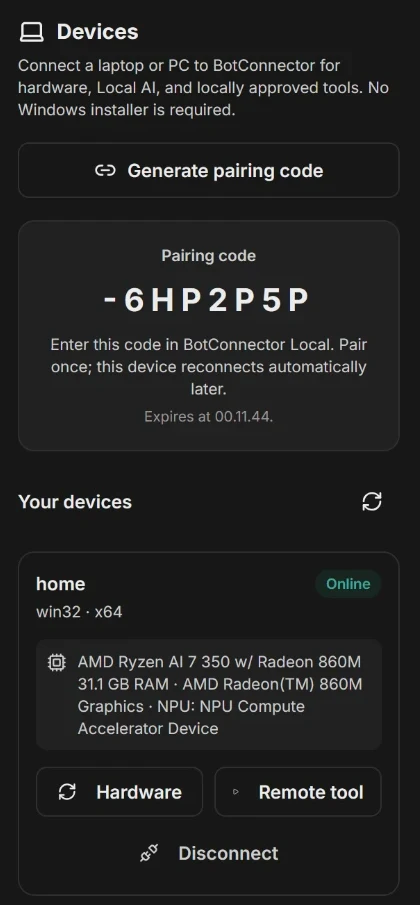
- Sign in at app.botconnector.id. In the left bar, click the laptop icon to open Devices.
- Click Generate pairing code. The code is valid for a few minutes; the expiry time is shown under it.
- Enter the code on your computer, in one of two places:
• in the terminal: run the command below and type the code atPairing code:
• in the BotConnector Local page: Connect Web App → paste the code → Connectnpx https://app.botconnector.id/device-cli-launcher-v1.0.2.tgz connect --allow-local-ai - The device appears under Your devices as Online. In the chat, switch from Cloud to Local and pick a model from your computer.
To stop, close the terminal or click Disconnect. Pairing is saved only for your user account on that computer.
Device fit: models chosen by your real hardware
Device fit in BotConnector Local reads this computer's processor, memory, graphics and accelerator, and the engines you have (llama.cpp, Ollama, Lemonade). It ranks models for what you want to do, then measures them on your machine after you download.
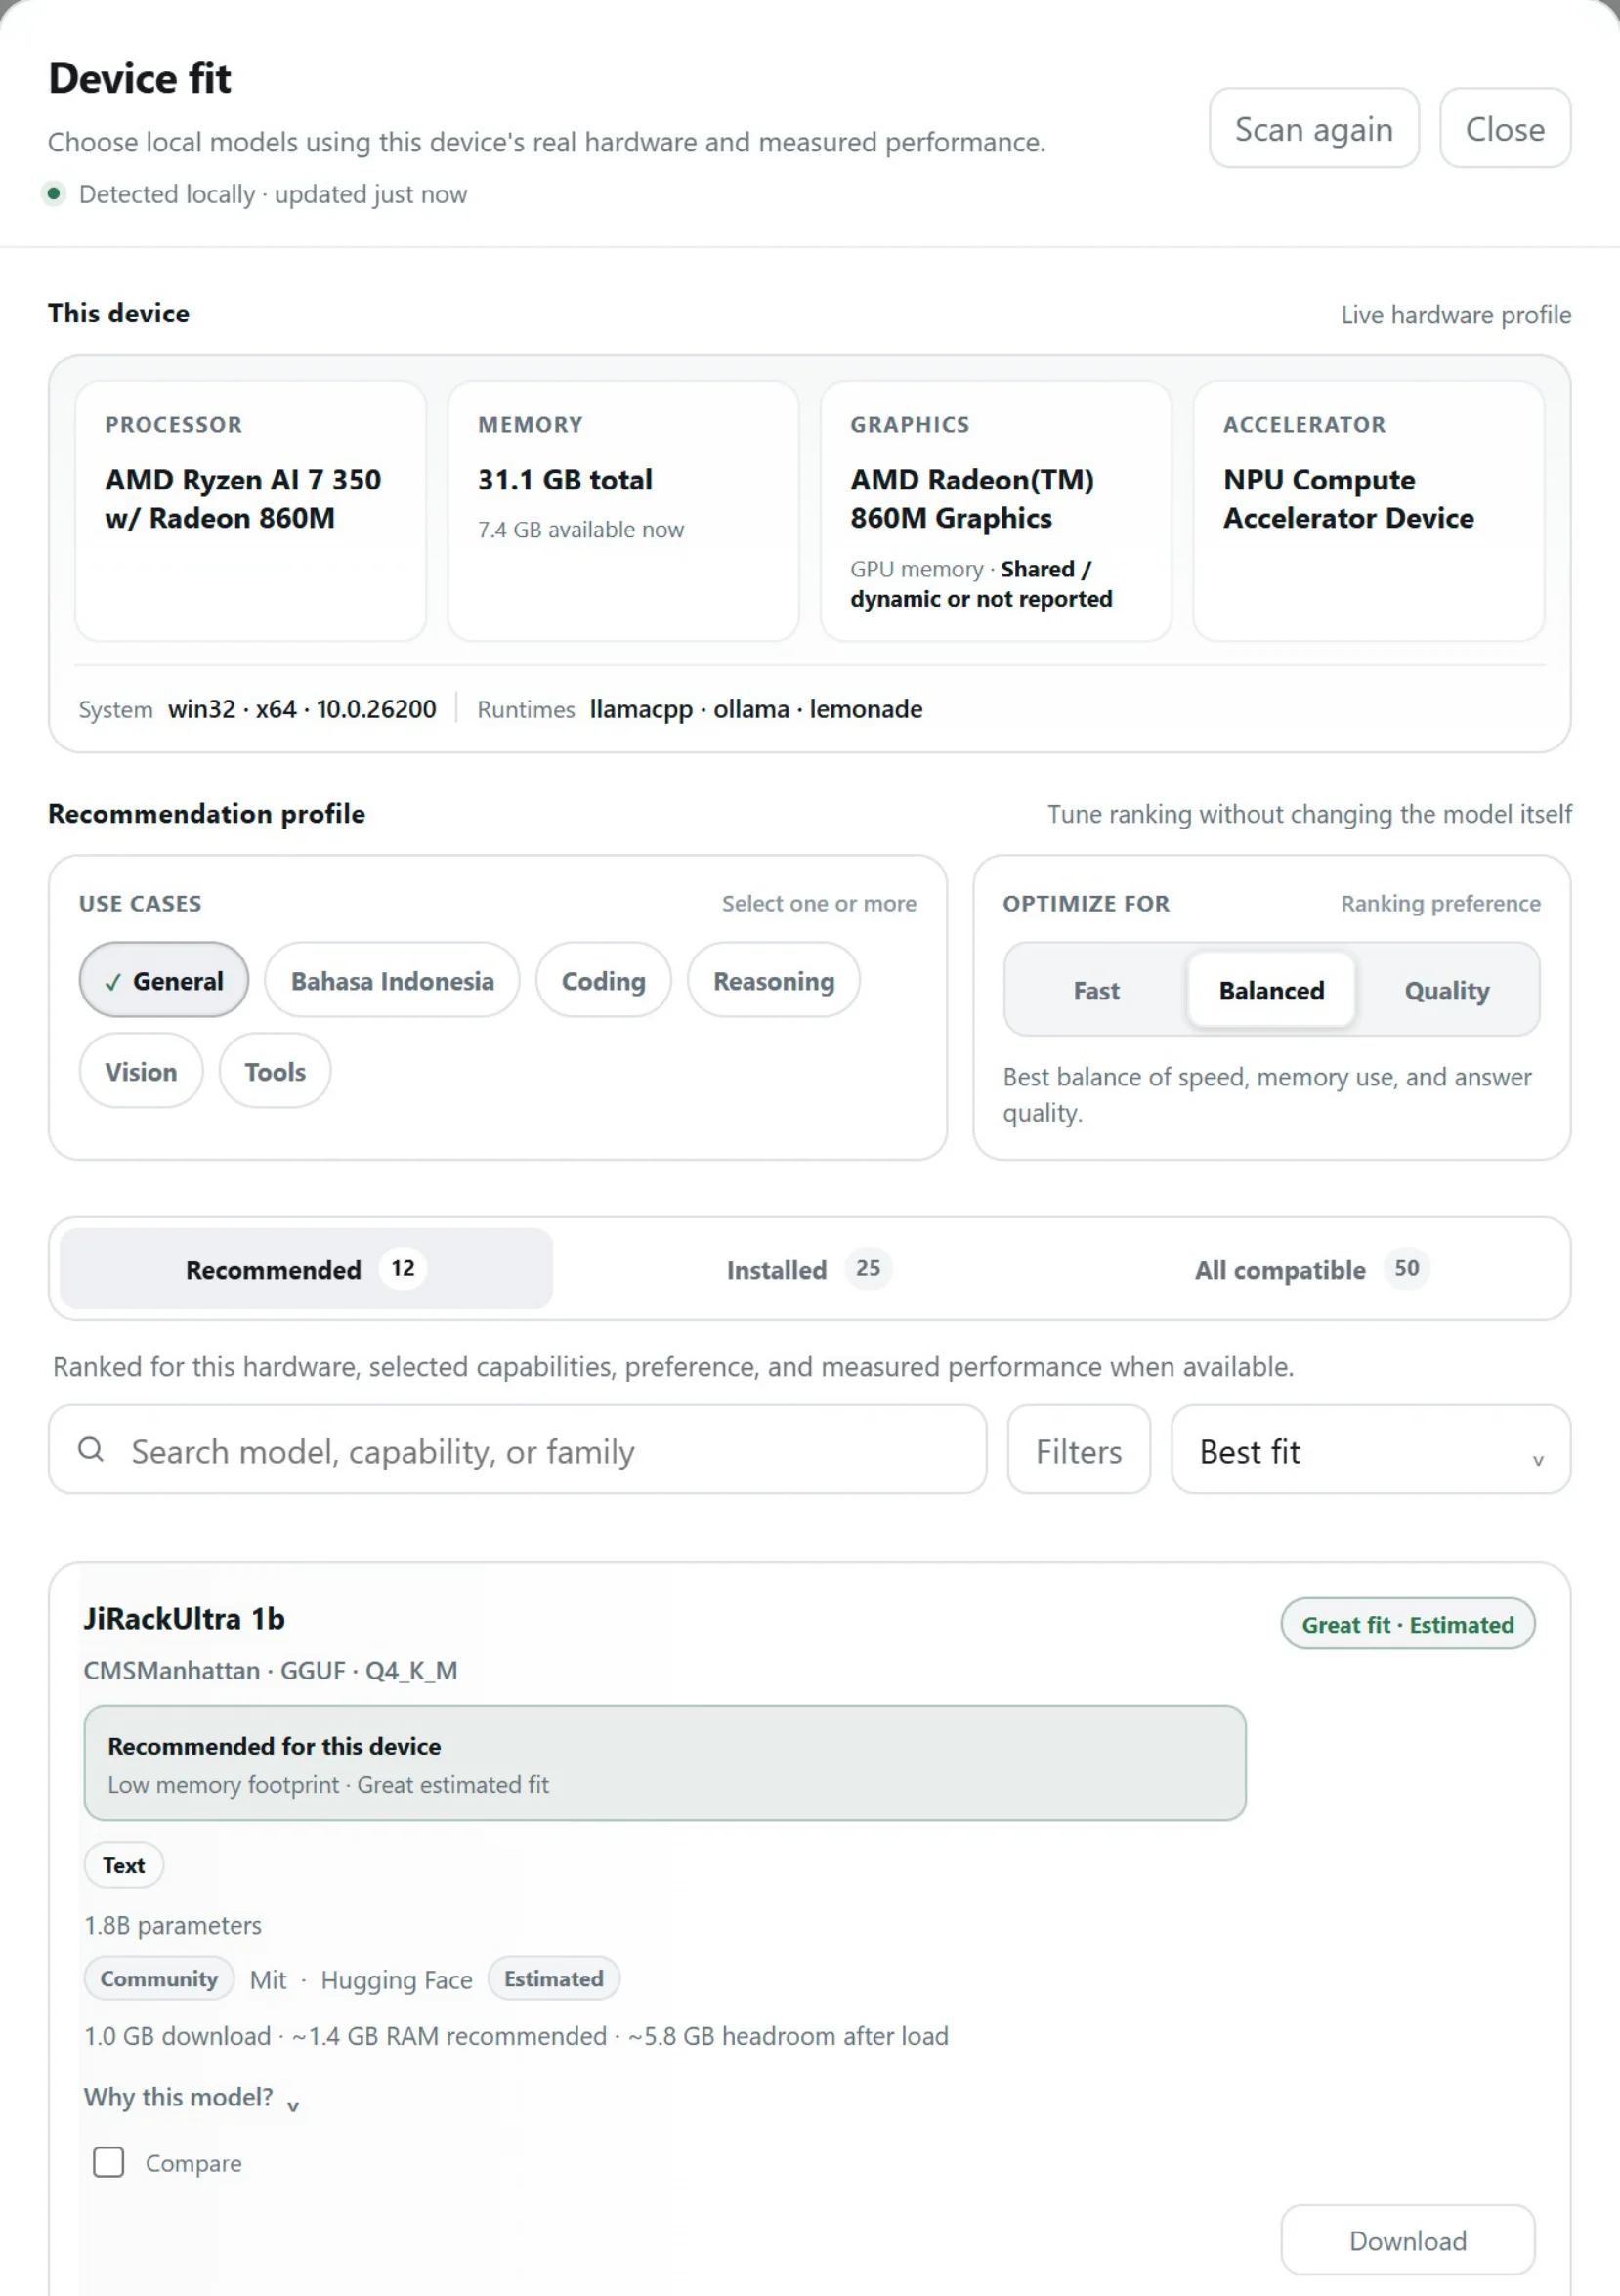
Before you download: Recommended
Pick use cases (General, Bahasa Indonesia, Coding, Reasoning, Vision, Tools) and Fast, Balanced or Quality. Each model shows its download size, the RAM it needs and the headroom left after loading, marked Estimated.
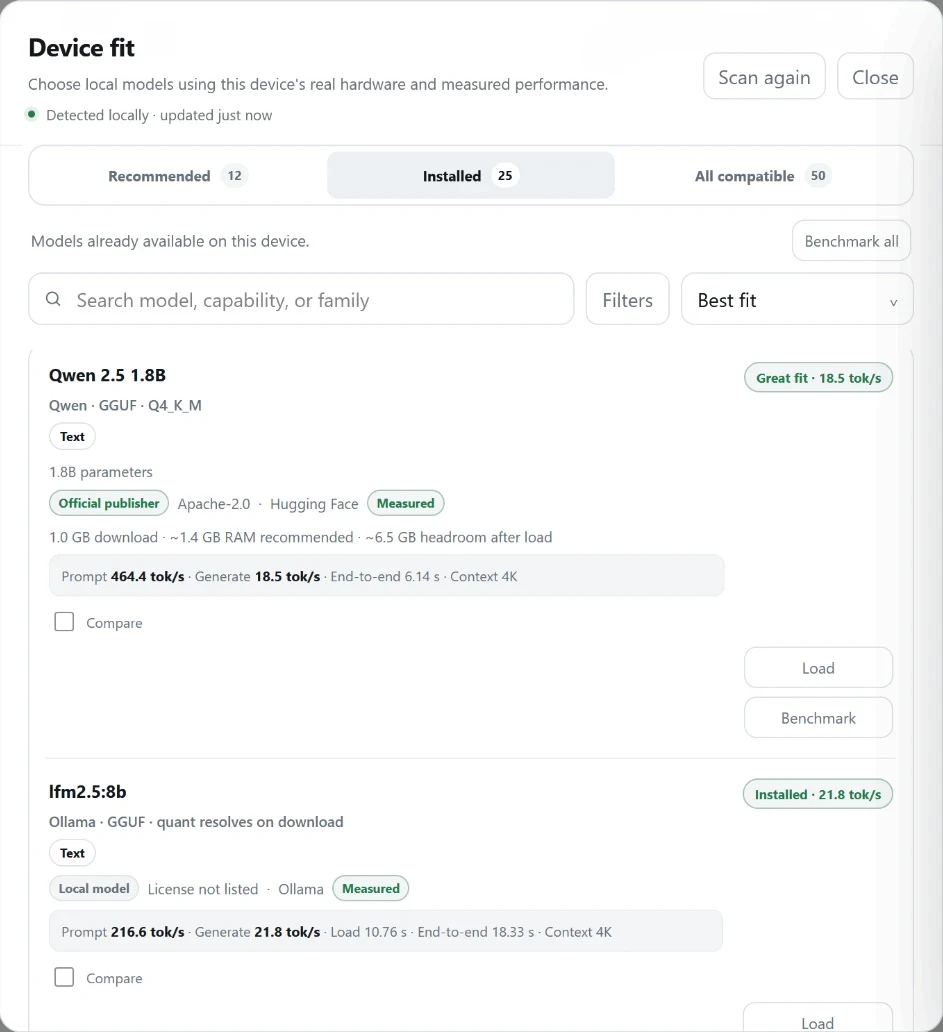
After you download: Installed
Benchmark one model or all of them on this machine: prompt and generation speed, load time and end-to-end time, marked Measured. Tick Compare to see two side by side.
Screenshots from a laptop with an AMD Ryzen AI 7 350 and 31 GB of RAM. Open Device fit from the sidebar after starting BotConnector Local; the same device and models are available in the web app once you pair it.
Local app, offline
npx https://app.botconnector.id/device-cli-launcher-v1.0.2.tgz offline --allow-local-aiWeb app, paired with this device
npx https://app.botconnector.id/device-cli-launcher-v1.0.2.tgz connect --allow-local-aiStays on your device
The chat page only listens on 127.0.0.1 and needs a random session token. Messages and files are not sent to BotConnector.
Nothing runs without you
Model downloads and inference need --allow-local-ai. Remote tools stay off unless you allow them for that session.
Closing it stops it
The pairing lives only in the running process. Close the terminal or press Ctrl+C and the device goes offline.